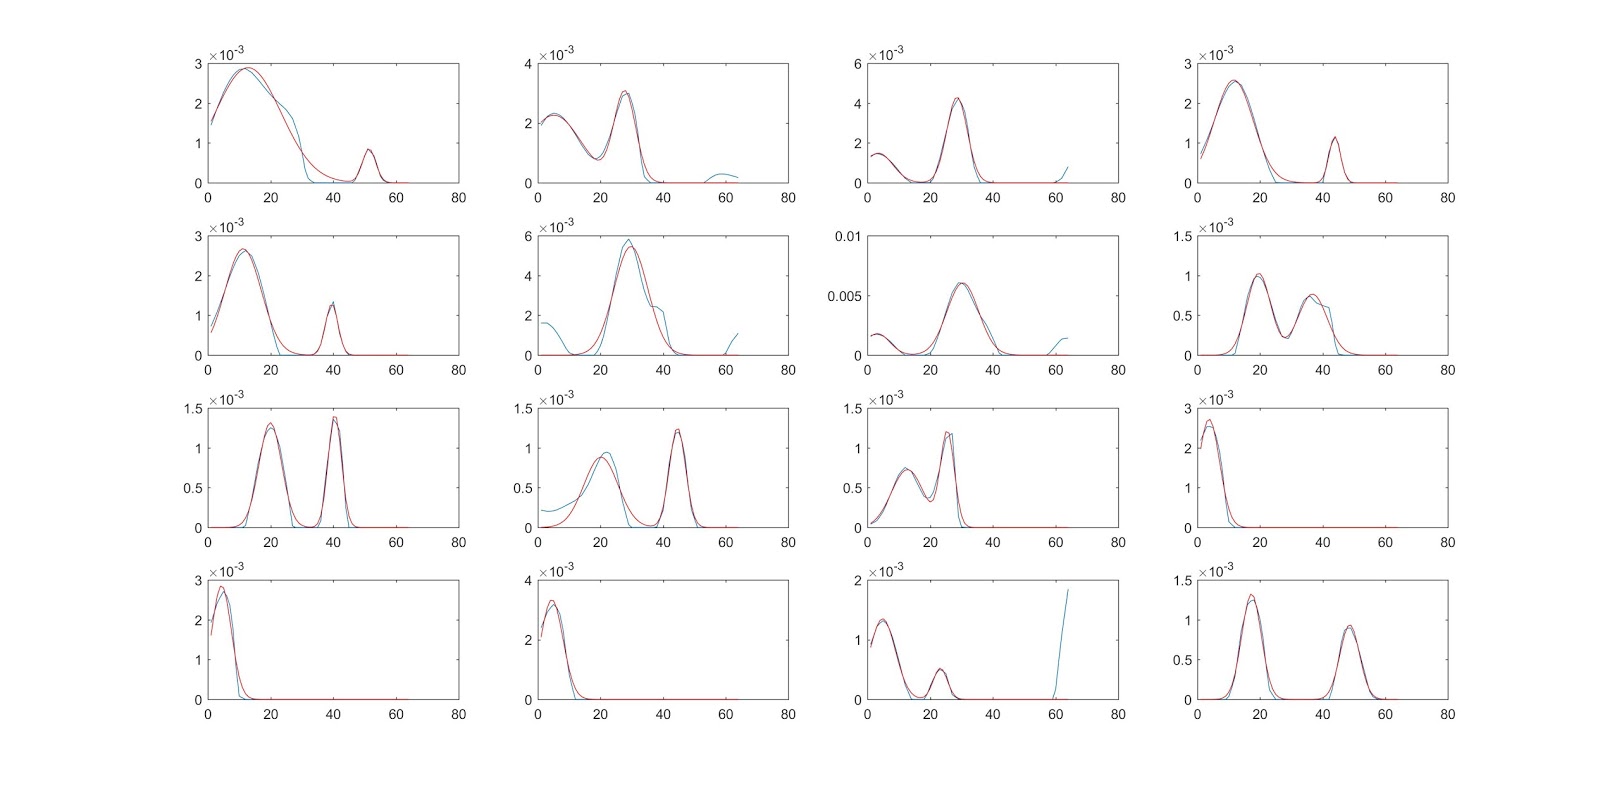
Summary:
I try to select 6 most possible models to predict:
ANN,
Boosted tree, Cubist, Random forest, SVM and Elastic Net.
As what I read last semester, these six are the best ones used to predict other kinds of data.
At this evening, I code for ANN model. Now the laptop is calculating and it has not finished yet. So I do not know if it is good or not for now. I will leave it calculating by itself. Tomorrow, I may get some results.
Codes:
## T2 Prediction
head(betapredict)
head(logmatch)
betaorigin=betapredict
logorigin=logmatch
logchange1=logorigin
betachange1=betaorigin
library(caret)
set.seed(1)
trainingrows=createDataPartition((1:3055), p=0.8, list=FALSE)
head(trainingrows)
trainlog=logchange1[trainingrows, ]
trainbeta=betachange1[trainingrows,]
testlog=logchange1[-trainingrows, ]
testbeta=betachange1[-trainingrows,]
library(earth)
library(kernlab)
library(nnet)
library(MASS)
parameter1=trainbeta$P1
parameter2=trainbeta$P2
parameter3=trainbeta$P3
parameter4=trainbeta$P4
parameter5=trainbeta$P5
parameter6=trainbeta$P6
ctr1=trainControl(method = "cv", number = 10)
nnetgrid=expand.grid(.decay=c(0, 0.01, 0.1), .size=c(1:10), .bag=FALSE)
set.seed(100)
nnettune=train(trainlog, parameter1, method="avNNet", tuneGrid = nnetgrid, trControl = ctr1,
preProcess = c("center", "scale"), linout = TRUE, trace = FALSE,
MaxNWts = 10*(ncol(trainlog)+1)+10+1, maxit=200)
nnettune
Tomorrow, I will continue to build models and compare them.
Results:
Model Averaged Neural Network
2447 samples
16 predictor
Pre-processing: centered (16), scaled (16)
Resampling: Cross-Validated (10 fold)
Summary of sample sizes: 2202, 2202, 2202, 2201, 2202, 2203, ...
Resampling results across tuning parameters:
decay size RMSE Rsquared
0.00 1 0.001182810 0.2659956
0.00 2 0.001178855 0.2652559
0.00 3 0.001176240 0.2700417
0.00 4 0.001171193 0.2758881
0.00 5 0.001171282 0.2757166
0.00 6 0.001175032 0.2719288
0.00 7 0.001169831 0.2771893
0.00 8 0.001170633 0.2768607
0.00 9 0.001173294 0.2730265
0.00 10 0.001174102 0.2723126
0.01 1 0.001202662 0.2380567
0.01 2 0.001202690 0.2380329
0.01 3 0.001202191 0.2388848
0.01 4 0.001201014 0.2403814
0.01 5 0.001208686 0.2342891
0.01 6 0.001192577 0.2520885
0.01 7 0.001187736 0.2564749
0.01 8 0.001188651 0.2550046
0.01 9 0.001189708 0.2548316
0.01 10 0.001190979 0.2544052
0.10 1 0.001212622 0.2285682
0.10 2 0.001211344 0.2293782
0.10 3 0.001209365 0.2291870
0.10 4 0.001211336 0.2291943
0.10 5 0.001211175 0.2295812
0.10 6 0.001204673 0.2362646
0.10 7 0.001203994 0.2369177
0.10 8 0.001202633 0.2369342
0.10 9 0.001203141 0.2373625
0.10 10 0.001204911 0.2364219
Tuning parameter 'bag' was held constant at a value of FALSE
RMSE was used to select the optimal model using the smallest value.
The final values used for the model were size = 7, decay = 0 and bag = FALSE.
The results come out now but R2 of training model is not very good. The largest is smaller than 0.3. It should be at least 0.7. I will try to figure it out today.
Results:
Model Averaged Neural Network
2447 samples
16 predictor
Pre-processing: centered (16), scaled (16)
Resampling: Cross-Validated (10 fold)
Summary of sample sizes: 2202, 2202, 2202, 2201, 2202, 2203, ...
Resampling results across tuning parameters:
decay size RMSE Rsquared
0.00 1 0.001182810 0.2659956
0.00 2 0.001178855 0.2652559
0.00 3 0.001176240 0.2700417
0.00 4 0.001171193 0.2758881
0.00 5 0.001171282 0.2757166
0.00 6 0.001175032 0.2719288
0.00 7 0.001169831 0.2771893
0.00 8 0.001170633 0.2768607
0.00 9 0.001173294 0.2730265
0.00 10 0.001174102 0.2723126
0.01 1 0.001202662 0.2380567
0.01 2 0.001202690 0.2380329
0.01 3 0.001202191 0.2388848
0.01 4 0.001201014 0.2403814
0.01 5 0.001208686 0.2342891
0.01 6 0.001192577 0.2520885
0.01 7 0.001187736 0.2564749
0.01 8 0.001188651 0.2550046
0.01 9 0.001189708 0.2548316
0.01 10 0.001190979 0.2544052
0.10 1 0.001212622 0.2285682
0.10 2 0.001211344 0.2293782
0.10 3 0.001209365 0.2291870
0.10 4 0.001211336 0.2291943
0.10 5 0.001211175 0.2295812
0.10 6 0.001204673 0.2362646
0.10 7 0.001203994 0.2369177
0.10 8 0.001202633 0.2369342
0.10 9 0.001203141 0.2373625
0.10 10 0.001204911 0.2364219
Tuning parameter 'bag' was held constant at a value of FALSE
RMSE was used to select the optimal model using the smallest value.
The final values used for the model were size = 7, decay = 0 and bag = FALSE.
The results come out now but R2 of training model is not very good. The largest is smaller than 0.3. It should be at least 0.7. I will try to figure it out today.